Fine-Tuning Lab
Fine-Tuning Lab
Datasets, LoRA, QLoRA, base-model choice, hyperparameters, Unsloth, evaluation, preference tuning and deployment — and when not to fine-tune at all. Every lab measures the base model before training and reports what the evaluation actually supports.
2 published · 10 planned
Foundations
LabWhat Fine-Tuning Actually IsComing soon
LabBuild a Fine-Tuning Dataset ProperlyComing soon
Adaptation methods
LabLoRA From First PrinciplesComing soon
LabQLoRA and 4-Bit Fine-TuningComing 31 Oct
LabChoosing the Right Base ModelComing 7 Nov
LabHyperparameters That Actually MatterComing 14 Nov
Train and evaluate
LabFine-Tune a Model End-to-End with UnslothComing 21 Nov
LabDid the Fine-Tune Actually Work?Coming 28 Nov
LabPreference Tuning and DPOComing 5 Dec
Production
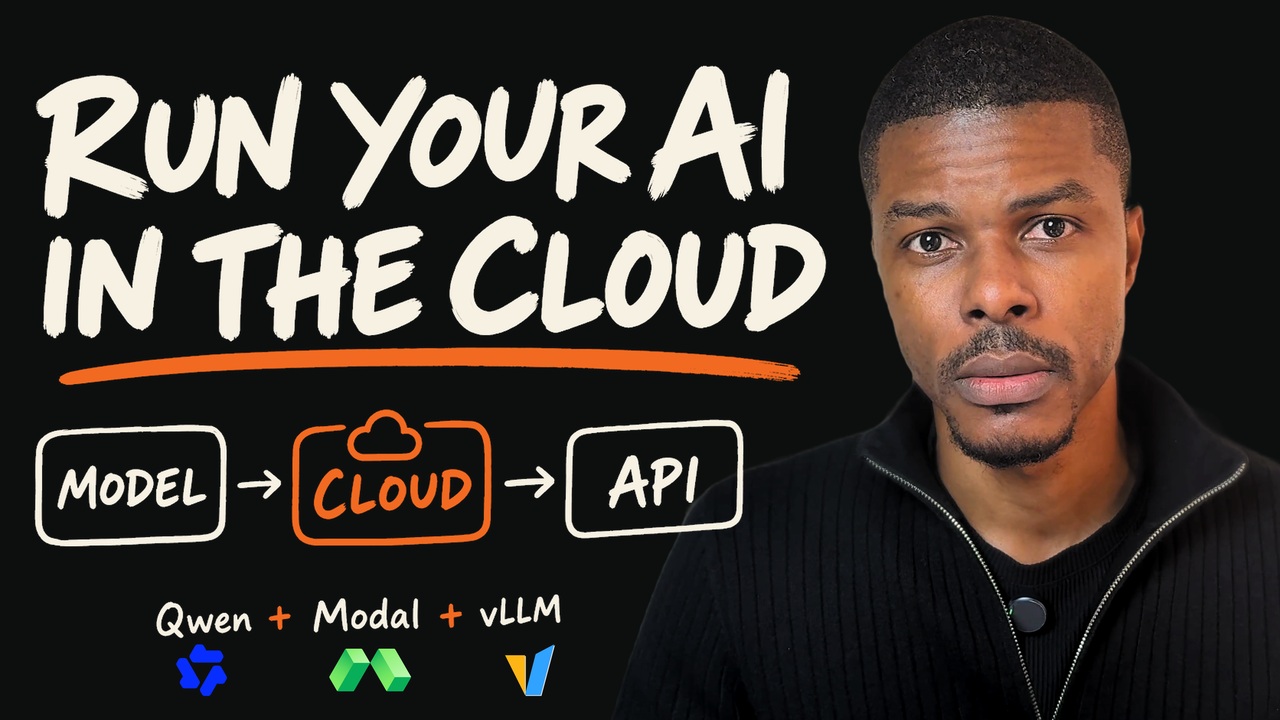 Deploy Your Own AI Model to the Cloud — Qwen + Modal + vLLMRun Qwen locally with Unsloth, then deploy it to an NVIDIA T4 on Modal with vLLM behind an authenticated API and call it from Python — with the cold-start wait, token usage, access checks and the ten-cent bill measured on screen.Lab · 40 min · 25 chapters · Article21 Oct 2026
LabFrom Fine-Tuned Model to ProductionComing 12 Dec